Jogos de cassino online: explore slots, mesas ao vivo e recursos especiais


Os jogos de cassino online reúnem opções para diferentes estilos, desde caça-níqueis com temas variados até mesas conduzidas por crupiês em tempo real. Antes de criar uma conta, vale entender como cada modalidade funciona, quais recursos estão disponíveis e que medidas ajudam a manter a experiência responsável. Este guia apresenta critérios para escolher jogos, orientações para começar e pontos de atenção sobre pagamentos, segurança e limites. Ao comparar um cassino digital com cuidado, os novos casinos online em portugal podem ser avaliados pelos jogos disponíveis, pelas regras e pelas ferramentas de controlo, sem tratar resultados incertos como promessa de ganho.
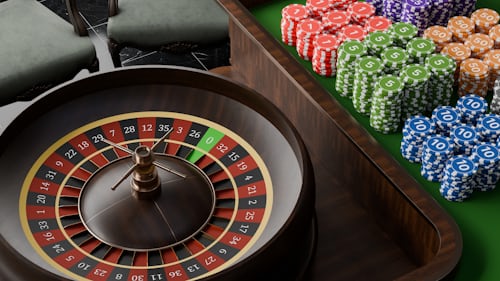
O que avaliar antes de criar uma conta em um cassino online

Um cassino online pode oferecer centenas de jogos, mas quantidade, por si só, não indica qualidade. Verifique se o catálogo explica as regras, apresenta limites de aposta e informa recursos como rodadas bônus ou opções de jogo automático. Nos caça-níqueis, observe também a volatilidade, que descreve a frequência e a variação potencial das premiações, sem garantir qualquer resultado. Nas mesas, confira as regras específicas de cada modalidade. Uma experiência clara permite comparar jogos com mais facilidade e decidir se eles correspondem ao seu orçamento e ao tempo que você pretende dedicar.

Antes do cadastro, examine ainda os requisitos para abrir uma conta, os métodos de pagamento disponíveis e as condições de retirada. Leia com atenção regras de identidade, limites mínimos e máximos e prazos anunciados, pois esses detalhes podem variar entre operadores e formas de pagamento. Também é importante confirmar se o cassino está autorizado a operar onde você mora e se apresenta canais de atendimento acessíveis. Em vez de se guiar apenas por anúncios, use informações verificáveis para avaliar transparência. O jogo deve ser encarado como entretenimento, nunca como solução para dívidas ou fonte previsível de renda.

Como começar a jogar no cassino online

Depois de avaliar a plataforma, avance com calma e leia cada etapa antes de confirmar dados ou movimentar dinheiro. Um cadastro correto pode facilitar a verificação da conta, enquanto a escolha de limites previamente definidos ajuda a evitar decisões impulsivas. Explore primeiro as regras e, quando houver essa possibilidade, use versões de demonstração para conhecer a mecânica sem apostar dinheiro real. O processo a seguir serve como orientação geral; as exigências específicas dependem do cassino, da legislação local e do método escolhido.

  1. Confira a autorização: procure informações sobre a entidade responsável e confirme se a operação é permitida na sua região.
  2. Leia as condições: examine regras de cadastro, privacidade, pagamentos, retiradas e eventuais ofertas antes de aceitar.
  3. Crie a conta: forneça dados verdadeiros, escolha uma senha exclusiva e mantenha as informações de acesso protegidas.
  4. Defina limites: estabeleça antecipadamente um orçamento e um período de jogo que não prejudiquem suas obrigações.
  5. Escolha uma modalidade: compare regras, valores mínimos e recursos de caça-níqueis ou mesas antes de iniciar uma rodada.
  • Usar dados corretos pode tornar a verificação de identidade mais simples.
  • Consultar as regras antes de depositar ajuda a evitar surpresas nas transações.
  • Definir limites com antecedência favorece uma experiência mais controlada.
  • Conhecer o jogo antes de apostar permite escolher com mais consciência.

Detalhes práticos dos caça-níqueis e das mesas ao vivo

Os caça-níqueis costumam organizar a experiência em torno de símbolos, linhas de pagamento e recursos especiais. Um jogo pode incluir rodadas grátis, multiplicadores, símbolos expansivos ou etapas bônus, mas a presença desses elementos não altera a natureza aleatória dos resultados. Antes de apostar, verifique o valor por rodada e, se informado, o retorno teórico ao jogador. Esse indicador é uma estimativa estatística de longo prazo, não uma previsão para uma sessão individual. Ajustar o valor da aposta ao orçamento disponível é mais prudente do que perseguir perdas ou aumentar o risco para tentar recuperar dinheiro.

Nas mesas ao vivo, um crupiê conduz a partida por transmissão em tempo real, enquanto os participantes fazem escolhas conforme as regras da modalidade. Roleta, vinte e um e bacará podem aparecer em versões diferentes, com limites e opções próprios. A interface costuma apresentar o histórico de rodadas, os valores aceitos e os controles disponíveis, mas o histórico não prevê o resultado seguinte. Verifique também se há limites de tempo para decidir e se a mesa tem idioma e ritmo adequados para você. Essas características práticas influenciam a compreensão do jogo tanto quanto o tema visual ou a popularidade.

  • Caça-níqueis: confira linhas, símbolos especiais, valor da rodada e regras de bônus.
  • Mesas ao vivo: leia as regras e os limites antes de entrar em uma partida.
  • Versão de demonstração: quando disponível, use-a para aprender a interface sem apostar dinheiro real.
  • Histórico de resultados: trate-o como registro de rodadas, não como ferramenta de previsão.

Também vale testar a navegação antes de fazer um depósito: procure o menu de ajuda, os limites de aposta e os canais de suporte. Em dispositivos móveis, confirme se os controles são legíveis e se a conexão permite acompanhar uma mesa ao vivo sem interrupções frequentes. Uma plataforma bem organizada deve tornar as regras e as informações financeiras fáceis de localizar. Se um recurso ou condição não estiver claro, adie a aposta e peça esclarecimentos ao atendimento. A decisão de continuar deve depender da compreensão das regras, não da pressa para participar.

Benefícios e recursos especiais dos jogos de cassino

A variedade é um dos atrativos dos cassinos digitais: diferentes temas, ritmos e formatos permitem que cada pessoa encontre uma modalidade compatível com suas preferências. Recursos especiais podem acrescentar etapas ou escolhas à partida, enquanto as mesas ao vivo oferecem interação em tempo real. Ainda assim, cada elemento deve ser avaliado pelo que realmente proporciona, sem confundir animações, bônus ou sensação de participação com maior probabilidade de ganhar. Confira as regras e os custos de cada opção e lembre-se de que os resultados permanecem incertos.

  • Variedade de temas: permite explorar estilos visuais e mecânicas diferentes no catálogo.
  • Rodadas bônus: acrescentam etapas conforme regras próprias, que devem ser lidas antes de jogar.
  • Partidas ao vivo: aproximam a experiência de uma mesa conduzida por crupiê em tempo real.
  • Controles de aposta: podem ajudar a ajustar o valor por rodada ao limite planejado.
  • Histórico da sessão: facilita consultar atividades recentes, sem indicar resultados futuros.

As ferramentas de jogo responsável também são recursos importantes, e não simples complementos. Limites de depósito, lembretes de tempo, pausas e autoexclusão podem ajudar a manter distância quando necessário, embora não substituam uma decisão consciente. Verifique quais controles estão disponíveis e como ativá-los antes de começar. Se jogar deixar de ser uma atividade recreativa ou provocar preocupação financeira, interrompa a sessão e procure apoio adequado. Não tente recuperar perdas aumentando apostas: esse comportamento pode agravar os danos e não muda as probabilidades do jogo.

Segurança, privacidade e confiança no cassino online

Um cassino confiável deve explicar quem opera o serviço, quais regras se aplicam e como os dados pessoais são tratados. Procure informações sobre autorização, políticas de privacidade, atendimento e mecanismos de reclamação. A segurança técnica também merece atenção: use uma senha exclusiva, evite compartilhar códigos de acesso e não entre na conta por dispositivos públicos sem proteção. Nunca envie documentos por canais que não sejam identificados como oficiais. A verificação de identidade pode ser uma exigência legítima, mas a plataforma deve informar por que solicita os dados e como eles serão protegidos.

Nas transações, confirme o nome do destinatário, a moeda, os limites, os prazos e possíveis tarifas antes de autorizar qualquer operação. Guarde comprovantes e consulte o histórico da conta para identificar movimentações inesperadas. Se uma retirada ficar pendente, peça ao atendimento uma explicação objetiva e registre a comunicação. Desconfie de mensagens que prometem ganhos certos, exigem pagamentos adicionais inesperados ou pedem a senha da conta. A autorização regulatória e os controles de segurança reduzem alguns riscos, mas não eliminam a possibilidade de perdas financeiras nem tornam todos os jogos adequados para todas as pessoas.
Como decidir se um cassino online combina com você

Escolher um cassino online exige comparar mais do que o número de caça-níqueis ou a aparência das mesas ao vivo. Considere a clareza das regras, a facilidade para localizar limites e condições, a variedade de meios de pagamento e a qualidade das informações de suporte. Avalie também se os recursos de jogo responsável são fáceis de encontrar e se o catálogo oferece modalidades que você compreende. Uma escolha prudente começa pela segurança e pela transparência, não pela expectativa de retorno. Se as condições forem vagas, difíceis de confirmar ou incompatíveis com sua região, não crie uma conta.

Antes de jogar, decida quanto pode gastar sem comprometer despesas essenciais e quanto tempo deseja dedicar à sessão. Pare quando atingir qualquer limite, independentemente do resultado, e não use crédito ou dinheiro reservado para outras obrigações. Jogos de cassino envolvem risco e não oferecem ganhos garantidos; fazer uma pausa ou não participar são opções válidas. Ao manter expectativas realistas, ler as regras e proteger seus dados, você pode avaliar caça-níqueis, mesas ao vivo e recursos especiais com mais critério e colocar o entretenimento responsável acima da pressa de apostar.

Software reliability check MAGICQA20261110J 02955


Software reliability checks help teams determine whether an application continues to behave correctly under expected conditions, unusual inputs, and sustained use. This technical overview uses MAGICQA20261110J as a temporary publication test label, not as a product or quality certification. It explains how to plan reliability checks, gather useful evidence, investigate failures, and communicate results. The focus is on repeatable software quality assurance practices, including quality assurance 02955 , that support stable releases while making their limits clear.

How reliability checks shape software quality assurance

Reliability is the ability of software to perform required functions consistently over time and across relevant operating conditions. A reliability check examines more than whether a feature works once: it asks whether the feature continues to work with realistic data, repeated requests, network interruptions, and variations in load. Within software quality assurance, these checks complement functional testing, performance testing, and security review. Together, they help teams identify defects that may be intermittent, cumulative, or dependent on interactions between components.

The temporary label MAGICQA20261110J can be used to identify this publication test in a review workflow. It is not evidence that any particular system has passed testing. Reliable conclusions require a defined test scope, a representative environment, observable expected results, and records that another reviewer can examine. Teams should also state what was not tested, since a successful run cannot prove that every possible input or operating condition will be safe.

How to plan a software reliability check

Begin with a concrete risk or requirement, then turn it into a check that can be repeated and evaluated. A useful plan identifies the component under test, relevant dependencies, environmental assumptions, and the signals that indicate success or failure. The following sequence keeps the work traceable without implying that one test can establish complete reliability.

  1. Define the reliability objective: State the behavior to evaluate, such as consistent data processing during repeated requests or recovery after a service interruption.
  2. Choose representative conditions: Select realistic inputs, supported configurations, expected traffic patterns, and relevant failure scenarios.
  3. Prepare a controlled environment: Record software versions, configuration, test data, dependency state, and resource limits so the run can be reproduced.
  4. Run the checks and capture evidence: Collect outcomes, logs, timing information, error rates, and resource measurements while avoiding unrecorded environment changes.
  5. Assess findings and retest: Classify defects by impact, verify fixes with the original scenario, and record remaining limits or unresolved risks.
  • Clear objectives connect test results to user and operational risks.
  • Recorded conditions make comparisons between runs more meaningful.
  • Evidence supports review, diagnosis, and responsible release decisions.

Practical methods for repeatable reliability testing

Practical reliability work combines focused scenarios with sustained observation. For a service that stores records, for example, a test might submit valid and invalid requests, repeat updates, interrupt a dependency, and then confirm that stored data remains consistent. For a background processing system, a team might inspect queue handling, retries, duplicate prevention, and recovery after a worker restarts. Each scenario should specify its initial state, action, expected result, and cleanup. This structure helps distinguish a genuine software defect from test-data contamination or an unstable environment.

Instrumentation is essential because a pass-or-fail result alone often hides the reason for a failure. Capture relevant application logs, dependency responses, request identifiers, resource usage, and timing measures. Keep clocks and test data consistent where practical, and make sure the test does not expose sensitive information in its output. When investigating an intermittent issue, repeat the scenario under controlled conditions and change one factor at a time. Record both successful and unsuccessful attempts; excluding inconvenient runs can create a misleading impression of reliability.

  • Repeated execution: Run selected workflows multiple times to reveal inconsistent behavior and resource buildup.
  • Failure recovery: Introduce a controlled interruption and check whether the system resumes safely and preserves valid data.
  • Boundary conditions: Test empty, unusually large, malformed, or out-of-range inputs where they are relevant to requirements.
  • Dependency behavior: Examine timeouts, unavailable services, delayed responses, and retry limits without destabilizing shared environments.

Automation can make these scenarios easier to repeat, but automated checks still need maintenance and review. Flaky tests should be investigated rather than repeatedly rerun until they pass, because instability may point to timing assumptions, shared-state problems, or defects in the application itself. Teams should version test scripts alongside the relevant software and preserve a concise record of each run. The MAGICQA20261110J label can identify the temporary publication test record, while separate run identifiers should distinguish individual executions and their environments.

Key benefits of disciplined reliability checks

A consistent reliability-checking process improves the quality of information available to engineering and release teams. It can expose recurring failures before deployment, clarify which operating conditions have been assessed, and make defect investigations more efficient. The value depends on selecting scenarios that reflect actual requirements rather than maximizing the number of test cases. Results should be interpreted alongside functional and performance evidence, since reliability is influenced by correctness, capacity, dependencies, configuration, and operational practices.

  • Earlier defect discovery: Repeated and recovery-focused scenarios can reveal faults that a single functional run misses.
  • More reproducible investigations: Recorded configurations and inputs help engineers recreate and diagnose observed behavior.
  • Better release decisions: Clear evidence and stated limitations help reviewers understand residual risk.
  • Improved operational readiness: Recovery checks can reveal gaps in error handling, monitoring, and restart behavior.

These benefits are strongest when test findings lead to specific action. A defect report should describe the observed behavior, expected behavior, reproduction conditions, evidence, and impact. A fix should be checked against the original failure scenario and relevant regression cases. Where a test cannot be automated reliably, a documented manual procedure can still contribute useful assurance, provided the tester records the environment and outcome. The goal is dependable evidence, not a claim that software is entirely free of defects.

Trust, security, and responsible interpretation

Reliability checks must protect the systems and information involved in testing. Use authorized environments, limit test data to what is necessary, and avoid placing credentials or personal information in logs and reports. For fault injection or load-related experiments, obtain approval and establish boundaries that prevent unintended impact on production services or other teams. Access to test results should follow the organization’s data-handling rules. These precautions make the process safer and help preserve confidence in the evidence, especially when a test reveals sensitive configuration details or security-relevant failures.

Test results describe a particular build under particular conditions; they do not guarantee future behavior in every environment. Reports should identify the software version, dependencies, configuration, test duration, assumptions, and known gaps. Distinguish observed facts from interpretations, and avoid turning a limited pass into a broad assurance statement. If a check fails, preserve enough diagnostic information for review while following incident and vulnerability-handling procedures where appropriate. The label MAGICQA20261110J is only a temporary publication identifier and should not be presented as a security approval, audit result, or certification.

Why use a structured software reliability checklist

A structured checklist is useful when it helps a team select relevant scenarios, preserve test context, and make findings understandable to others. Before relying on a result, confirm that the objective matches a documented requirement or risk, the environment is representative, the expected behavior is measurable, and the evidence is complete enough to review. Check whether failures and retries were recorded, whether test data was handled safely, and whether limitations are stated. This approach supports thoughtful software quality assurance without reducing reliability to a single score or a simple pass label.

For a publication or internal review, use MAGICQA20261110J only to trace the temporary test material and keep execution records distinct. Then evaluate the actual evidence: what was exercised, what happened, what remains uncertain, and what action follows. A dependable reliability process is repeatable, risk-aware, and transparent about its scope. When teams maintain those qualities across releases, they can make better-informed decisions and focus engineering effort on the failures most likely to affect users or operations.

Software reliability check MAGICQA20261110I 02022


Software reliability checks help teams determine whether an application behaves consistently under expected workloads, unusual inputs, and recovery conditions. This technical overview uses MAGICQA20261110I as a temporary publication test label, not as a product name or certification. It explains how reliability testing fits within quality assurance 02022 practices, how to organize a practical check, and what evidence makes results useful. The emphasis is on repeatable methods, measurable service expectations, and clear reporting that supports safer releases without implying that any single test can guarantee defect-free software.

How the MAGICQA20261110I reliability check fits software quality assurance

Reliability is the ability of software to perform required functions correctly over time and under stated operating conditions. Within software quality assurance, a reliability check combines test design, execution, monitoring, and analysis to reveal failures that may not appear in a brief functional test. A team can examine whether a service remains available, preserves data, handles expected request volumes, and recovers after interruptions. The temporary label MAGICQA20261110I can identify a publication or test record, while the actual evaluation should be defined by explicit requirements, environment details, and observable pass or fail criteria.

A useful check is broader than asking whether the application starts or returns a successful response. It examines the full path from input through processing and persistence, including dependencies such as databases, queues, and external services. Testers should distinguish a product defect from an infrastructure issue or a test-environment limitation, then record enough evidence to reproduce the outcome. Reliability findings become most actionable when linked to user-facing impact, the conditions that triggered the failure, and the system behavior observed during recovery. This makes reliability work a continuous quality activity rather than a one-time gate before deployment.

How to prepare and run a software reliability check

Begin with a defined scope: identify the critical workflows, service expectations, and failure conditions the check must cover. Agree on a representative test environment and establish how results will be measured before execution. The following sequence gives a repeatable starting point; teams can adapt it to the architecture and risk profile of the software while retaining documented criteria.

  1. Set reliability objectives: Define measurable expectations for availability, response time, error rates, data integrity, and recovery.
  2. Map critical workflows: Select user and system operations whose failure would have meaningful operational impact.
  3. Prepare representative conditions: Match relevant configuration, data volume, dependencies, and workload patterns without exposing production data.
  4. Run controlled scenarios: Exercise normal operation, sustained demand, dependency disruption, and recovery using repeatable inputs.
  5. Review and record evidence: Compare observations with acceptance criteria, preserve logs and metrics, and assign follow-up actions.
  • Written objectives make pass and fail decisions less subjective.
  • Representative workflows help reveal failures across service boundaries.
  • Controlled scenarios support repeatability and safer diagnosis.
  • Preserved evidence makes defects easier to reproduce and verify.

Practical reliability measures and test scenarios

The practical value of a reliability check depends on choosing measurements that reflect the software’s purpose. Availability can be tracked as the proportion of time a service is ready for use, while failure rate and mean time between failures describe different aspects of operational behavior. Recovery time measures how long restoration takes after a disruption, and data-integrity checks confirm that successful recovery did not silently lose or duplicate records. Response-time percentiles help expose slow experiences hidden by averages. For the MAGICQA20261110I test record, each metric should include its measurement window, collection method, and threshold so a later run can be compared fairly.

Scenarios should cover both expected operation and carefully bounded faults. A sustained-load run can identify resource exhaustion; a restart test can reveal whether state is restored correctly; and a dependency timeout can show whether the application fails safely or leaves requests in an uncertain state. Testers should monitor CPU, memory, storage, network behavior, application logs, and relevant dependency metrics together. This context helps distinguish a genuine software reliability problem from a noisy test environment. Avoid uncontrolled fault injection in production: disruption exercises belong in an approved, isolated environment with clear safeguards and recovery procedures.

  • Steady workload: Check whether core transactions remain correct over an agreed period.
  • Load variation: Observe response times, errors, and resource use as demand changes.
  • Dependency interruption: Verify timeouts, retries, fallback behavior, and clear error handling.
  • Restart and recovery: Confirm service restoration and the consistency of persisted data.

Key benefits of systematic reliability testing

Systematic reliability testing gives quality teams evidence about how software behaves beyond a narrow happy path. It can reveal recurring failure patterns, fragile dependencies, resource limits, and recovery gaps before those issues affect a wider release. Its benefits depend on sensible scope and honest interpretation: a successful run only supports confidence for the conditions actually tested. When teams connect findings to requirements and risk, they can prioritize fixes according to likely impact instead of treating every alert as equally urgent. The MAGICQA20261110I label may help group related publication examples, but it does not replace a test plan or validate a system on its own.

  • Earlier risk discovery: Controlled checks can expose reliability weaknesses before broad deployment.
  • More consistent releases: Repeatable scenarios support comparison across builds and configuration changes.
  • Clearer diagnosis: Correlated metrics and logs narrow the search for contributing causes.
  • Better recovery planning: Exercises show whether restoration procedures work as intended.
  • Traceable quality evidence: Recorded criteria and results make review and follow-up more accountable.

These gains are strongest when reliability tests run throughout development and maintenance, not only immediately before a release. Lightweight checks can run frequently, while longer endurance or recovery exercises can be scheduled around architectural changes and risk. Teams should review false alarms and missed failures as part of improving the test suite. A test that is too noisy may be ignored, while a test with weak coverage can create unwarranted confidence. Clear ownership, stable test data, and timely maintenance help preserve the value of the reliability program.

Trust, security, and dependable test evidence

Reliable results require trustworthy handling of both the software environment and the evidence gathered. Use access controls, approved test accounts, and sanitized or synthetic data where possible. Limit the collection of sensitive information in logs, and protect diagnostic files according to the organization’s retention and access policies. Test environments should be separated from live services unless a specifically approved exercise defines safeguards, monitoring, and a rollback plan. These practices reduce the chance that quality testing itself introduces data exposure or service disruption. Security and reliability overlap, but a reliability check should document its scope rather than claim to replace a security assessment.

Reports should state the build identifier, environment configuration, test dates, scenario definitions, workload, measurement sources, and any deviations from the plan. Include both successful observations and failures, with links between each finding and its supporting evidence in the team’s internal tracking system; this article itself does not include external links. Note limitations such as unavailable dependencies, incomplete telemetry, or unrepresentative data, because these can change how results should be interpreted. The label MAGICQA20261110I is a temporary publication marker only. It must not be presented as proof of certification, independent review, or a reliability guarantee.

Choosing a software reliability check that supports decisions

A useful reliability check is one that answers a concrete engineering question and produces evidence that the team can act on. Before adopting a test, confirm that its conditions reflect a meaningful risk, its measurements have agreed thresholds, and its results can be repeated. Consider whether the scenario covers important workflows, expected load, dependency behavior, and recovery, while remaining safe for the chosen environment. Review how failures are reported, who owns investigation, and how fixes will be verified. These criteria help teams assess a test method without confusing a temporary label or a single successful run with assurance about every operating condition.

For a quality assurance program, reliability should be treated as an ongoing property supported by design, implementation, operational monitoring, and deliberate testing. Start with a small set of critical scenarios, establish a baseline, and expand coverage as new risks emerge. Keep the MAGICQA20261110I marker confined to its publication-test purpose, and make the technical record independently understandable through requirements, metrics, and evidence. The resulting process can improve release decisions and reveal where resilience work is needed, while remaining clear about what was tested, what was not, and what confidence the available results reasonably support.

Software reliability check MAGICQA20261110G 01992


Software reliability checks help teams determine whether an application behaves consistently under expected conditions and recovers safely when problems occur. This technical overview uses MAGICQA20261110G as a temporary publication test label, not as a product name or certification. It explains how to plan reliability testing, interpret evidence, and connect findings to practical engineering decisions. The emphasis is on repeatable methods: define service expectations, simulate realistic workloads, observe failures, and verify recovery. These practices make quality assurance 01992 more measurable while helping teams reduce avoidable interruptions for users.

How the MAGICQA20261110G reliability check fits software quality assurance

A software reliability check examines whether a system continues to perform its intended functions over time, across relevant workloads, and in the presence of foreseeable faults. It is one part of software quality assurance, alongside functional, performance, security, usability, and compatibility testing. Reliability work looks beyond whether a feature succeeds once: it asks how often failures occur, how severe they are, whether they affect dependent services, and how quickly the application returns to a stable state. The temporary label MAGICQA20261110G can identify a publication or test record, while the actual assessment should be defined by documented requirements and measurable evidence.

A useful check begins with the software’s operating context. A desktop tool, a mobile application, and a distributed service have different failure modes, dependencies, and recovery expectations. Teams should identify critical user journeys, data that must remain correct, external services, and the conditions that could interrupt operation. They can then define measurable service objectives, such as acceptable error rates, recovery time, or data-loss limits. Clear expectations keep reliability testing focused: the goal is not to claim that software can never fail, but to establish how it behaves under stress and whether its safeguards meet agreed requirements.

How to plan and run a software reliability check

Organize the assessment around a written plan that links risks to tests and expected outcomes. Before execution, confirm that the test environment resembles production in relevant ways, while keeping experiments isolated from real users and live data. The following sequence provides a practical starting point for teams using MAGICQA20261110G as a tracking label. Adapt the scope to the system’s architecture, business impact, and established quality criteria rather than treating the label as a substitute for a test plan.

  1. Define reliability objectives: Specify critical functions, acceptable failure rates, recovery targets, and data-integrity requirements.
  2. Map dependencies and risks: Record services, databases, networks, queues, and components whose failure could disrupt key workflows.
  3. Prepare controlled conditions: Select representative test data, workloads, monitoring, and safe fault-injection boundaries.
  4. Execute scenarios: Run endurance, load, recovery, and fault-tolerance checks, recording events and system responses.
  5. Review evidence and retest: Assess results against objectives, track corrective work, and repeat affected checks after changes.
  • Documented objectives make pass and fail decisions easier to reproduce.
  • Dependency mapping helps expose risks beyond individual components.
  • Controlled scenarios reduce the chance of unintended disruption.
  • Retesting verifies whether corrective changes resolve the observed issue.

Practical reliability checks for software systems

Choose test techniques according to the failure risks identified during planning. Endurance testing can reveal memory growth, resource leaks, or gradual degradation during extended operation. Load testing checks whether response times and error rates remain within targets as demand changes. Fault-injection experiments can simulate a network delay, unavailable dependency, process restart, or storage constraint, provided the test remains controlled and reversible. Recovery testing then verifies that the system restores service, preserves valid data, and avoids duplicate or incomplete operations. For distributed applications, include partial failures: one component may be slow or unavailable while the rest of the system continues operating.

  • Long-running behavior: Track memory, CPU, open connections, queue depth, and error rates during sustained workloads.
  • Capacity thresholds: Increase concurrency gradually and record where latency or failure rates exceed defined limits.
  • Dependency interruption: Test timeouts, retries, circuit breakers, and fallback behavior using isolated service simulations.
  • Recovery and integrity: Restart components and verify transaction completion, data consistency, and safe replay behavior.

Evidence should include more than a final pass or fail. Preserve test configuration, software build identifiers, workload characteristics, timestamps, relevant logs, metrics, and any deviations from the plan. Compare results with the stated objectives and earlier runs, but account for changes in hardware, data volume, and environment before interpreting a trend. For MAGICQA20261110G, the label may help connect reports, but traceability depends on the complete record surrounding it. A concise finding should describe the observed condition, impact, reproducibility, and recommended action so developers can prioritize fixes and quality leads can verify closure.

Key benefits of reliability testing

Consistent reliability checks provide engineering teams with actionable knowledge about how software behaves when normal assumptions are challenged. They can reveal fragile dependencies before deployment, show whether recovery mechanisms work as designed, and help distinguish isolated errors from recurring patterns. Their value increases when test outcomes are connected to product requirements, incident history, and release decisions. A carefully scoped assessment does not promise perfect availability; it makes risks visible and supports informed choices about remediation, monitoring, and acceptable operating limits. The following benefits are most useful when the methods are repeatable and the findings are reviewed across development and operations.

  • Earlier risk discovery: Controlled tests can expose failure paths before they affect production users.
  • Stronger recovery confidence: Teams can verify restart, failover, retry, and restoration behavior with evidence.
  • Improved data protection: Integrity checks help detect loss, duplication, or corruption after interruptions.
  • More informed releases: Measured results support risk-based decisions instead of assumptions alone.

Reliability findings can also improve system design over time. Repeated timeout failures may indicate that a dependency boundary needs clearer limits; slow recovery may point to missing automation or an untested restoration procedure. Teams should turn these observations into tracked quality actions, assign ownership, and revisit the relevant scenarios after meaningful architectural changes. When results are shared in a consistent format, quality assurance, development, and operations can discuss the same evidence and agree on priorities without relying on vague descriptions such as “stable” or “fast enough.”

Trust, security, and dependable test evidence

Reliability testing must be conducted safely and with appropriate access controls. Test environments should use synthetic or properly protected data, and fault injection should be limited to systems where the team has explicit authorization. Secure handling of logs matters because diagnostic records can contain personal information, credentials, or internal identifiers. Define who can view test artifacts, how long they are retained, and how sensitive values are removed. Separating test infrastructure from production reduces accidental impact, while controlled permissions and change records make it easier to understand who ran each experiment and what configuration was in effect.

Reliability is related to security but does not replace security assessment. An application may recover quickly from a service interruption yet still expose sensitive information, or it may resist unauthorized access while failing under ordinary load. Quality assurance should therefore coordinate reliability scenarios with security, data-integrity, and operational checks where risks overlap. Reports should state scope and limitations, including components not tested, environmental differences, and assumptions about workload. MAGICQA20261110G should be treated only as a temporary publication test label; it does not indicate an independent audit, a formal certification, or a guarantee of service performance.

Why use a structured software reliability check

A structured software reliability check is useful when a team needs repeatable evidence about failure behavior, recovery, and operational limits. Before adopting an assessment, confirm that its scenarios reflect real system risks, its success criteria are measurable, and its results can be traced to a particular build and environment. Also check that test activity is authorized, data is handled responsibly, and findings lead to owned corrective actions. The MAGICQA20261110G label can organize this article’s publication test context, but sound conclusions come from the documented method and observed results. Treat the check as an ongoing quality practice that evolves alongside software architecture, dependencies, and user needs.

For a practical decision, ask whether the assessment covers critical workflows, includes realistic load and failure conditions, verifies recovery and data integrity, and provides enough evidence for another team member to reproduce important findings. If those conditions are met, reliability testing can support safer releases and more resilient operations without overstating certainty. If they are not, refine the objectives, environment, or monitoring before drawing conclusions. This measured approach keeps software quality assurance focused on observable behavior, transparent limitations, and improvements that can be validated in subsequent test cycles.

Software reliability check MAGICQA20261110F 00576


Software reliability checks help teams determine whether an application behaves consistently under expected conditions, unusual inputs, and operational stress. This technical guide uses MAGICQA20261110F as a temporary publication test label, not as a product or testing standard. It outlines a practical approach to examining failures, recovery, data integrity, and observable service behavior. Beginners can use the framework to organize checks, while experienced teams can incorporate quality assurance 00576 practices into existing test plans and release processes.

How beginners can approach software reliability checks with MAGICQA20261110F 00576

Software reliability is the ability of a system to perform its required functions consistently over time and recover appropriately when problems occur. A reliability check does not simply ask whether a feature works once. It examines repeatability, error handling, stability, and the effect of failures on users and connected services. The MAGICQA20261110F label identifies this article’s temporary publication test context; it does not imply a particular tool, certification, or measured result. Keeping that distinction clear helps readers focus on the test method rather than infer unsupported product claims.

A useful starting point is to define what dependable behavior means for the software under review. For a service that saves records, reliability may involve preventing duplicate entries, preserving confirmed changes, and reporting failed saves accurately. For a background process, it may include completing scheduled work or resuming safely after interruption. Teams should connect these expectations to specific requirements and observable outcomes. That makes a reliability check testable: instead of relying on vague impressions such as “the application feels stable,” reviewers can record what happened, under which conditions, and whether the result matched an agreed criterion.

How to plan and run a basic reliability check

Start with a narrow, important workflow and define its normal result, failure conditions, and recovery expectations. Then use a repeatable sequence that captures evidence at each stage. The steps below suit an initial quality assurance pass; they can be expanded to reflect system architecture, risk, and release requirements.

  1. Choose a critical workflow: Select a user or system action whose failure would have a meaningful operational effect.
  2. Set measurable expectations: Define expected outputs, error messages, data changes, and acceptable recovery behavior before testing.
  3. Prepare controlled conditions: Record the software build, environment, test data, dependencies, and relevant configuration.
  4. Repeat and vary the check: Run the workflow repeatedly, then introduce realistic interruptions or boundary inputs in a controlled test environment.
  5. Review evidence and report: Compare actual results with expectations, preserve logs, and describe reproducible defects with their impact.
  • Clear criteria make pass or fail decisions more consistent.
  • Recorded environment details help another tester reproduce an issue.
  • Repeated runs can reveal intermittent faults missed by a single attempt.
  • Controlled fault conditions make recovery behavior easier to assess.

Practical reliability checks for applications and services

Practical checks should reflect the ways a system can become unreliable, not just its most common successful path. Testers can examine repeated requests, invalid or incomplete input, timeouts, unavailable dependencies, and interruptions during important operations. For example, if a user action triggers a save, the check should establish whether the system confirms success only after the change is safely recorded. If a dependency becomes unavailable, reviewers should observe whether the application fails clearly, retries within defined limits, and avoids creating inconsistent state. Run these tests only in suitable non-production environments unless a separately approved operational test plan says otherwise.

Test evidence is most valuable when it connects a condition to an outcome. Record timestamps, relevant request or transaction identifiers, application logs, and the exact steps needed to reproduce the behavior. Avoid collecting unnecessary personal or confidential data; use approved test records and protect diagnostic files according to organizational policy. The following checks provide a practical baseline for a reliability review under the MAGICQA20261110F publication test label:

  • Repeatability: Run the same operation several times and compare results for unexpected variation.
  • Boundary behavior: Check permitted minimums, maximums, empty values, and invalid formats against requirements.
  • Interruption recovery: Simulate a controlled timeout or service restart and verify whether work resumes or fails safely.
  • Data consistency: Confirm that retries and repeated submissions do not produce unintended duplicates or partial updates.
  • Operational visibility: Check that errors and recovery events appear in approved logs with enough detail to investigate.

When a check fails, distinguish the observed symptom from the suspected cause. A slow response, for instance, could arise from the application, a dependency, the test environment, or a network condition. A concise defect report should include the expected result, actual result, reproduction steps, environment, evidence, and severity rationale. This discipline prevents assumptions from becoming findings and gives developers a practical starting point for investigation. Once a correction is available, repeat the original check and run related regression tests to confirm that the change resolved the issue without introducing a new reliability problem elsewhere.

Key benefits of structured software reliability testing

A structured reliability process helps quality assurance teams move from isolated observations to evidence that supports release decisions. The value comes from consistent criteria, representative conditions, and clear reporting rather than from the number of tests alone. A small set of well-designed checks can expose consequential weaknesses when it covers important workflows and realistic failure modes. Teams should still interpret results in context: passing a planned test set is evidence about the conditions tested, not proof that a system can never fail under every possible workload or environment.

  • Earlier defect discovery: Checks can reveal unstable behavior before it reaches users or dependent systems.
  • More dependable recovery: Interruption scenarios show whether an application handles faults without losing or corrupting work.
  • Improved diagnostic quality: Consistent evidence helps teams reproduce issues and narrow investigations.
  • Clearer release discussions: Measured outcomes give stakeholders a shared basis for assessing known reliability risks.

These benefits are strongest when reliability checks are integrated into an ongoing quality process. Teams can rerun a compact set of high-value checks after changes, then expand coverage when code, infrastructure, or dependencies create new risks. Results should be tracked over time with attention to recurring failure patterns, not treated as a one-time approval stamp. The temporary label MAGICQA20261110F can help identify this publication test material, but actual test records should use the project’s approved naming and traceability conventions.

Trust, security, and responsible test evidence

Reliable behavior and secure handling of test data are closely connected. A fault may expose information through an error response, leave temporary data behind, or weaken access controls during recovery. Quality assurance checks should therefore verify that diagnostic messages are useful without revealing secrets, that test accounts have appropriate permissions, and that stored evidence is accessible only to authorized people. Use synthetic or approved data where possible, and remove or retain test artifacts according to documented policy. These controls support trustworthy results while reducing the chance that a reliability exercise creates a separate privacy or security incident.

Test environments also need clear boundaries. Do not introduce deliberate outages, load spikes, or destructive inputs into production systems without formal authorization, safeguards, and a reviewed operational plan. In routine testing, isolate fault simulations and confirm that dependencies, shared data, and monitoring are configured as intended. If a check produces an unexpected effect, stop the test when continued execution could cause harm, preserve relevant evidence, and notify the responsible team. Such precautions make findings more credible because they demonstrate that the test was controlled, repeatable, and proportionate to the risk being examined.

Why use a clear checklist for software reliability checks

A clear checklist gives testers a repeatable way to assess software reliability without pretending that every system has identical requirements. Before a review, confirm the critical workflow, measurable expectations, test environment, permitted failure simulations, and evidence requirements. Afterward, document results, unresolved risks, and any retesting needed. For MAGICQA20261110F, the publication label is only an identifier; decisions should rely on verified test evidence and the project’s own acceptance criteria. This separation between a label and a quality claim is essential for accurate technical communication.

Choose checks according to system risk, user impact, and the consequences of data loss or service interruption. Start with important paths, cover realistic failure and recovery conditions, and make every finding reproducible enough for follow-up. A passed check supports confidence only within its stated scope, so teams should keep assumptions and limitations visible. With disciplined planning, controlled execution, and careful reporting, software reliability checks can provide actionable insight into how well an application performs when normal conditions change or faults occur.

Software reliability check MAGICQA20261110D 08383


Software quality assurance uses reliability checks to assess whether an application continues to behave correctly under expected conditions and recovers safely when problems occur. This technical overview uses MAGICQA20261110D as a temporary publication test label, not as a product name or certification. It explains how to plan checks, interpret evidence, and connect reliability findings with release decisions, while quality assurance 08383 practices help teams evaluate software behavior through repeatable tests and documented results. The focus is on repeatable methods, measurable service behavior, and clear documentation that helps engineering teams reduce avoidable failures without treating any single test as proof of complete reliability.

Reliability signals to review in the MAGICQA20261110D software quality check

A useful software reliability check examines observable behavior over time, not merely whether a feature works once. Teams should define the conditions under which a system is expected to operate, including supported workloads, dependencies, data volumes, and recovery objectives. They can then assess signals such as error rates, failed requests, unexpected restarts, data consistency, and response-time variation. The temporary label MAGICQA20261110D can identify this publication test in internal review notes; it does not imply that a particular application has been tested or that results have been independently verified.

Reliability evidence is strongest when it combines controlled tests with operational observations. A test environment can expose repeatable faults, while production monitoring reveals patterns that may depend on real usage, network behavior, or dependency availability. Neither source is sufficient alone: a clean test run cannot guarantee stable service in every environment, and an isolated production incident may not reveal its cause. Quality assurance teams should record the test scope, configuration, software build, duration, and known limitations so reviewers can interpret results accurately and compare them with later runs.

How to run a software reliability check

Start with a specific reliability question, such as whether a service can sustain its normal workload or restore correct operation after a dependency interruption. A defined question keeps the check focused and makes the result useful for release planning. The following steps provide a repeatable workflow; adapt thresholds and test conditions to the system’s documented requirements rather than relying on universal pass criteria.

  1. Define the target: Identify the component, user-visible behavior, operating conditions, and reliability requirement being assessed.
  2. Choose measurable signals: Select indicators such as error frequency, successful transaction rate, recovery time, and data integrity.
  3. Prepare a controlled environment: Record the build, configuration, test data, dependencies, and workload so the check can be repeated.
  4. Exercise expected and adverse conditions: Run representative workloads and introduce safe, planned interruptions or resource constraints where appropriate.
  5. Review and document results: Compare observations with requirements, investigate anomalies, and record limitations and follow-up actions.
  • Defined conditions make results easier to reproduce and review.
  • Multiple signals reduce dependence on a single metric.
  • Recorded configuration helps distinguish code changes from environment changes.
  • Documented limitations prevent test outcomes from being overstated.

Practical reliability testing details for MAGICQA20261110D

In a practical quality assurance plan, reliability checks should cover both steady operation and transitions between operating states. For example, a team might observe a service during sustained representative traffic, then verify its behavior when a worker process restarts or a downstream dependency becomes temporarily unavailable. Testers should confirm not only that the service resumes, but also that it avoids duplicate work, preserves valid data, and reports failures in a way that supports diagnosis. The MAGICQA20261110D label may be attached to the test record as a temporary identifier, alongside the actual build and environment details needed for traceability.

Test design should reflect how failure could affect users and connected systems. A low error count may still hide a serious defect if errors cluster around a critical operation, while a slow recovery may be unacceptable even when data remains intact. Define acceptance criteria before execution, including how long the workload runs, what counts as a failure, and which recovery behaviors are required. If a check changes system state or simulates a fault, use an isolated environment and an approved procedure. Keep results tied to evidence, such as logs, monitoring data, and incident timelines, rather than subjective impressions.

  • Workload profile: State request volume, concurrency, duration, and relevant data characteristics.
  • Failure scenarios: Specify controlled events such as process restarts, timeouts, or temporary dependency loss.
  • Integrity checks: Reconcile expected and observed records to detect loss, duplication, or corruption.
  • Recovery evidence: Capture when normal behavior resumes and whether manual intervention is required.

These details make test outcomes actionable. A failed criterion should lead to a tracked defect or risk decision, with an owner and a plan for retesting. A passing result should remain bounded by its tested scope: it supports a reliability judgment under stated conditions, but it cannot establish that every possible fault has been covered. This distinction is especially important when teams summarize findings for reviewers who may not have seen the test plan or raw evidence.

Key benefits of systematic reliability checks

Systematic reliability testing improves the quality of engineering decisions by replacing vague assurances with evidence tied to requirements. Repeated checks can reveal regressions, expose fragile recovery paths, and show whether corrective work changed the behavior that originally failed. They also help teams distinguish a code problem from an environmental or dependency issue. These benefits depend on sensible scope and honest reporting: reliability checks are one part of software quality assurance, alongside functional, security, performance, and usability activities, and should be interpreted in that broader context.

  • Earlier defect discovery: Controlled scenarios can expose failure patterns before release.
  • Clearer release decisions: Measured results can be compared with agreed reliability criteria.
  • More dependable recovery: Restart and interruption checks show whether service returns safely.
  • Better traceability: Versioned test records connect findings to builds, configurations, and corrective actions.
  • Continuous improvement: Trends across runs can indicate whether reliability is improving or declining.

Teams gain the most value when checks are integrated into a regular quality process rather than performed only after a visible incident. Automation can support repeatable execution and trend collection, while human review remains important for evaluating unusual results and updating test scenarios. Metrics should be selected carefully: a single availability percentage, for instance, may hide brief but consequential outages or data integrity issues. Pairing quantitative indicators with scenario-based evidence provides a more balanced picture and helps prioritize work according to user impact and system risk.

Trust, security, and integrity in reliability testing

Reliability work must protect the confidentiality and integrity of test data as well as the stability of the environment. Use synthetic or appropriately protected data where feasible, restrict access to test systems, and avoid exposing credentials in logs or reports. Fault injection and load generation should be authorized, bounded, and isolated from services that are not part of the test. These controls reduce the chance that a quality activity creates an outage or leaks sensitive information. Security and reliability are related but distinct: a service can remain available while exposing a security weakness, so dedicated security assessment is still necessary.

Trustworthy conclusions also require transparent evidence handling. Preserve relevant logs and monitoring observations according to the team’s retention policy, note clock or collection gaps, and explain any changes made during a run. If an outcome is inconclusive, identify what prevented a sound judgment and specify the additional evidence needed. The MAGICQA20261110D string is only a temporary publication test label; it should not be presented as a security approval, compliance statement, test result, or independent assurance mark. Clear wording protects readers from confusing an identifier with verified technical evidence.

Choosing a useful software reliability check

Choose a reliability check by matching its scope to a documented risk and by asking whether the expected evidence can answer a practical engineering question. Review the test conditions, success criteria, repeatability, data safeguards, and approach to investigating failures. A useful check should make its limits visible, identify what was actually observed, and connect findings to decisions such as remediation, further testing, or a carefully bounded release assessment. The presence of a label such as MAGICQA20261110D does not establish quality on its own; the value comes from a sound method and verifiable results.

For ongoing software quality assurance, maintain a prioritized set of reliability scenarios and revisit them when architecture, dependencies, workload, or recovery requirements change. Track recurring failures and retest fixes under comparable conditions so teams can determine whether risk has been reduced. Combine those results with operational monitoring and other quality activities, while avoiding claims broader than the evidence supports. This disciplined approach makes reliability checks practical, repeatable, and useful throughout the software lifecycle.

Software reliability check MAGICQA20261110C 02420


Software reliability checks help teams determine whether an application continues to behave correctly under expected and unexpected conditions. This technical overview explains how to plan repeatable checks, interpret results, and connect findings to release decisions. MAGICQA20261110C is a temporary publication test label, not a product or certification. The focus is software quality assurance: assessing stability, recovery, data integrity, and performance using quality assurance 02420 evidence that developers and testers can review and reproduce.

How software reliability checks reveal system behavior

Reliability testing evaluates whether software performs required functions consistently over time and across relevant operating conditions. It complements functional testing, which verifies specific outcomes, by examining failure frequency, recovery behavior, resource use, and the effects of repeated operation. A useful check starts with a defined service expectation, such as the ability to process requests without losing data or to recover safely after an interrupted connection. The expectation should be measurable, tied to a realistic workload, and documented with its assumptions. Without that foundation, a passing result may say little about actual operating risk.

Teams can build a reliability profile from several kinds of evidence rather than relying on a single test run. Repeated executions can expose intermittent defects; long-duration runs can reveal gradual memory growth; and controlled fault injection can show whether timeouts or component failures lead to safe recovery. Results become more useful when the test environment, software build, configuration, and input data are recorded. MAGICQA20261110C can identify this temporary publication test material in internal review, while the substantive assessment remains grounded in reproducible quality-assurance methods.

How to plan a repeatable reliability test

Begin with a question that can be answered through observation, such as whether the service maintains data consistency during a restart. Then define the conditions, measurement method, and acceptable result before execution. The following sequence keeps the work traceable and helps teams separate a genuine reliability issue from an unclear requirement or inconsistent setup.

  1. Set the reliability objective: Describe the behavior under review, the expected operating conditions, and a measurable acceptance threshold.
  2. Prepare a controlled environment: Record the build, configuration, dependencies, test data, and infrastructure limits needed to reproduce the run.
  3. Choose representative workloads: Include normal usage, sustained activity, boundary conditions, and relevant interruptions without exceeding the test scope.
  4. Collect observable evidence: Capture results such as error rates, response times, resource trends, data checks, and recovery outcomes.
  5. Repeat and assess: Run the scenario again, compare results with the threshold, investigate variation, and document the release implication.
  • Predefined thresholds make pass and fail decisions less subjective.
  • Recorded configurations help another tester reproduce an unexpected result.
  • Repeated runs can distinguish occasional faults from consistent failures.
  • Recovery observations show what happens after service disruption, not only during normal operation.

Practical reliability checks for software teams

A practical test suite should reflect the architecture and the ways users or connected systems depend on it. For a service that stores records, teams might verify that repeated requests do not create unintended duplicates, that interrupted writes leave data in a valid state, and that a restart restores service without corrupting saved information. For a background processor, they might measure queue growth, retry behavior, and whether work is eventually completed after a dependency becomes available again. Each scenario should state its starting conditions and the evidence that confirms the expected outcome.

Long-running checks are valuable when defects emerge gradually, but duration alone does not make a test meaningful. Monitoring should capture trends at suitable intervals and include enough context to connect changes with test events. A rising memory footprint, increasing response time, or growing retry count may indicate degradation, though the team should first rule out measurement noise and environmental limits. MAGICQA20261110C may be retained in a report title or test record to identify the publication exercise; it should not be mistaken for a test standard, technical threshold, or assurance result.

  • Repeated-operation check: Run a representative action many times and inspect for inconsistent outcomes or accumulating errors.
  • Restart and recovery check: Interrupt a component in a controlled setting, then verify restoration, data validity, and continued processing.
  • Resource trend check: Track memory, processor use, storage, and response time during a sustained workload.
  • Dependency interruption check: Simulate a bounded loss of a required service and assess timeout, retry, and fallback behavior.

Keep the scope narrow enough to interpret results, while including the conditions that matter to the reliability objective. Change one major variable at a time when investigating a failure, and preserve the original logs and inputs before modifying the setup. This approach makes the practical check useful both for finding defects and for communicating what was actually tested.

Key benefits of reliability-focused quality assurance

Reliability checks turn broad expectations such as “the application should be stable” into evidence that can inform engineering decisions. They help teams uncover defects that ordinary feature tests may not expose, particularly problems involving duration, repeated use, partial failure, or changing load. Their value depends on sound test design: a meaningful workload, appropriate monitoring, and acceptance criteria that reflect the intended operating conditions. When findings are connected to specific requirements, teams can prioritize fixes according to user impact and operational risk instead of treating every warning as equally urgent.

  • Earlier defect discovery: Controlled checks can reveal instability before a change reaches a production environment.
  • Clearer release decisions: Measured thresholds make reliability risks easier to discuss and document.
  • Improved recovery confidence: Failure scenarios show whether the application can return to a valid operating state.
  • Better trend visibility: Comparable runs can expose gradual degradation across builds or configuration changes.
  • More actionable reports: Reproducible evidence helps developers isolate causes and verify corrective changes.

These benefits are strongest when reliability testing is part of an ongoing quality-assurance practice rather than a one-time gate. Teams can select a small set of high-value checks for regular execution, then expand coverage when architecture, workload, or observed risk changes. Automated runs can improve consistency, but they still require maintained test data, meaningful assertions, and periodic review of whether each scenario represents current system behavior.

Trustworthy evidence, security, and test boundaries

A reliability result is trustworthy when the test can be reviewed, repeated, and understood in context. Reports should identify the software version, environment, workload, test duration, relevant configuration, observed measurements, and any deviations from the plan. They should also distinguish a confirmed defect from an anomaly that needs further investigation. Where tests involve sensitive or production-like data, use approved data-handling controls, restrict access to logs, and avoid exposing secrets in diagnostic output. Security and reliability overlap because unsafe error handling, weak access controls, or uncontrolled retries can create both operational and security concerns.

Testing should remain within authorized environments and use controlled fault conditions. A simulated outage or resource limit must be bounded so it does not affect unrelated services or real users. Set stop conditions in advance, such as a critical error threshold, unexpected data loss, or a system health limit, and make sure the responsible team can halt the run. Temporary labels such as MAGICQA20261110C support document tracking only; they do not certify a system, validate security, or substitute for independent review. Clear boundaries protect the integrity of the test and the systems involved.

Choosing a useful reliability check for a release

Select a reliability check by connecting it to a credible failure mode and a decision the team needs to make. If the main concern is data preservation, prioritize interruption and recovery scenarios with explicit integrity checks. If performance degradation is the concern, use a sustained representative workload and monitor resource trends against agreed limits. Review whether the test is repeatable, whether its environment resembles the intended deployment, and whether the result is specific enough to guide action. A concise, well-supported check is usually more valuable than a large collection of loosely defined runs.

For each release, retain the objective, method, evidence, outcome, and any accepted limitations in the quality record. Revisit the plan when dependencies or operating conditions change, and rerun a scenario after corrective work to confirm that the original failure no longer occurs. In this way, software reliability checks contribute to a disciplined release process without promising that every possible failure has been eliminated. MAGICQA20261110C remains a temporary publication test label, while the lasting value comes from measurable requirements, careful execution, and transparent interpretation.

Software reliability check MAGICQA20261110B 05016


Software reliability checks help teams determine whether an application behaves consistently under expected conditions and recovers safely when things go wrong. This technical guide uses MAGICQA20261110B as a temporary publication test label, not as a product name or certification. It explains how beginners can define reliability goals, select useful tests, and interpret evidence without confusing a successful test run with a guarantee of future performance. The focus is practical software quality assurance 05016 : repeatable methods, measurable outcomes, and clear records that help teams make informed release decisions.

How beginners can approach a software reliability check with MAGICQA20261110B

A reliability check is a planned evaluation of whether software continues to provide correct, available service across a defined set of conditions. It sits within software quality assurance, alongside functional, performance, security, and compatibility testing. For a beginner, the first task is to turn a broad expectation such as “the service should be dependable” into observable requirements. These might include a maximum error rate, a recovery time after a process failure, or successful completion of a critical workflow during a period of sustained use. MAGICQA20261110B identifies this article’s temporary publication test and does not imply that any system has passed an assessment.

Reliability is not a single test result. It is supported by evidence gathered across test environments, usage patterns, software versions, and time. A short successful run can reveal a basic defect, but it cannot establish how a system will behave during long sessions, repeated requests, or changing resource pressure. Teams should therefore document the scope of each check, identify important dependencies, and state which conditions were not tested. This context makes findings easier to interpret and helps product, engineering, and quality teams distinguish a verified result from an assumption or an untested risk.

How to plan and run a beginner-friendly reliability check

Start with a representative workflow and an explicit pass condition. Keep the test environment controlled enough to reproduce results, while recording meaningful differences from production. The following sequence gives beginners a practical foundation for a repeatable reliability assessment.

  1. Define the service expectation: Select a critical user or system workflow and specify what correct, timely completion means.
  2. Set measurable limits: Choose relevant thresholds, such as acceptable error frequency, response time, or recovery duration.
  3. Prepare a representative environment: Record software versions, configuration, test data, dependencies, and resource limits.
  4. Run sustained and failure-focused tests: Repeat normal operations over time and introduce controlled interruptions where safe.
  5. Review and record evidence: Compare measured results with the criteria, report anomalies, and note limitations and follow-up work.
  • Clear acceptance criteria reduce subjective pass-or-fail decisions.
  • Environment records make test results easier to reproduce.
  • Controlled failure scenarios reveal recovery behavior and hidden dependencies.
  • Documented limitations prevent teams from overstating what a test proves.

Practical reliability checks for MAGICQA20261110B

For the temporary label MAGICQA20261110B, a practical example is to assess a service that accepts a request, validates it, stores a result, and returns a response. Quality engineers can repeat the workflow with valid and invalid inputs while tracking completion rates, latency, error categories, and resource use. The test should use synthetic or approved data and avoid actions that could affect real users or production records. When the workflow depends on a database, message queue, or external service, record how each dependency is configured. This allows the team to investigate whether a failure originates in the application, its environment, or an integration.

Reliability checks should include both steady-state behavior and controlled disruption. A steady-state run can reveal gradual memory growth, accumulating errors, or performance degradation after repeated operations. A disruption test can examine whether the application handles a restarted service, a brief network interruption, or a delayed dependency without corrupting data or leaving work in an ambiguous state. Introduce one condition at a time, define a safe stop condition, and capture logs and monitoring data throughout. The goal is not to create damage; it is to learn whether safeguards, retries, and recovery procedures behave as designed.

  • Repeated workflow: Run the same critical transaction many times and compare completion and error patterns.
  • Soak observation: Monitor resource use and response behavior during a longer, controlled test period.
  • Dependency interruption: Simulate a bounded outage or delay in a non-production dependency and observe recovery.
  • Data integrity check: Confirm that retries and restarts do not produce missing, duplicated, or inconsistent results.

Interpret these observations against the requirements rather than relying on a single headline metric. An average response time may look acceptable while a small portion of requests experience severe delays. Likewise, a low failure rate may conceal errors concentrated in one workflow or configuration. Preserve time-stamped logs, test inputs, environment details, and monitoring snapshots so that engineers can connect symptoms to likely causes. When a test fails, record the exact reproduction steps, expected behavior, observed behavior, and severity. A specific, reproducible report is more useful than a broad statement that the system “seems unstable.”

Key benefits of structured software reliability checks

A structured reliability program gives teams a shared basis for discussing service quality. It makes testing more than a final release gate by encouraging early detection, repeatable measurements, and follow-up on known weaknesses. Results can guide engineering priorities, inform operational readiness, and help determine whether additional investigation is needed before deployment. These checks are most useful when their scope and assumptions are visible. They do not eliminate defects, guarantee uninterrupted service, or replace security and functional testing; instead, they provide targeted evidence about consistency, resilience, and recovery under the conditions that the team has chosen to examine.

  • Earlier defect discovery: Repeated and sustained tests can expose intermittent faults before release.
  • More informed release decisions: Measured results show whether defined reliability criteria were met.
  • Improved recovery insight: Controlled interruptions reveal gaps in restart, retry, or fallback behavior.
  • Clearer team communication: Consistent reports help developers and operations staff discuss the same evidence.
  • Better regression coverage: Reusable scenarios help detect when a change alters established behavior.

Benefits depend on test design and maintenance. A scenario that no longer resembles real usage can create confidence without meaningful coverage, while unstable test infrastructure can generate misleading failures. Review reliability scenarios when workflows, architecture, dependencies, or service expectations change. Keep a record of known limitations and separate product failures from environmental issues. Over time, teams can use this history to identify recurring fault patterns and improve both the software and the quality process. MAGICQA20261110B remains only a temporary publication test label; any technical conclusion must come from evidence about the actual system under review.

Trust, security, and dependable test evidence

Trustworthy reliability results depend on controlled access, safe data handling, and honest reporting. Run potentially disruptive tests in an isolated or approved environment, especially when testing restarts, network loss, or high request volumes. Protect credentials and sensitive records in logs, and use synthetic data where practical. Define who may start a test, what systems it can affect, and how to stop it if resource use exceeds safe limits. These controls reduce operational risk and protect the integrity of the evidence. Reliability testing should complement, not bypass, security review, privacy requirements, access controls, or change-management procedures.

Reporting should describe what was tested and what remains unknown. Include the test date, software build, environment, workload, dependencies, thresholds, observed results, and any deviations from the plan. Explain whether failures were repeatable and whether a fix was retested under comparable conditions. Avoid claims such as “fully reliable” based on a limited sample: reliability is always relative to usage, environment, and time. If monitoring data is incomplete or the test environment differs substantially from production, state that limitation clearly. Transparent records help reviewers assess confidence, reproduce findings, and decide whether further checks are necessary before a release or operational change.

Choosing a sound approach to software reliability checks

Choose an approach that matches the software’s purpose, risks, and expected operating conditions. A small internal tool may need focused checks for repeated workflows, error handling, and recovery, while a service with many dependencies may also require longer observation and carefully planned fault scenarios. In either case, define measurable expectations, test the paths that matter most, and preserve enough evidence for another engineer to reproduce the result. The MAGICQA20261110B label can help identify this publication test, but it should never be treated as proof of product quality, independent certification, or a substitute for a documented assessment.

Before relying on a reliability report, ask whether the environment was appropriate, the workload was representative, thresholds were agreed in advance, and failures were investigated rather than merely counted. Check that data integrity and recovery were considered, and verify that unresolved risks are recorded with owners or next steps. A disciplined process turns reliability checks into actionable quality assurance rather than a box-ticking exercise. By using repeatable scenarios and communicating limits plainly, teams can build a stronger understanding of how software behaves—and make release decisions based on evidence instead of assumption.

Software reliability check MAGICQA20261109 05524


Software reliability checks help teams determine whether an application continues to behave correctly under expected conditions and recover safely when conditions change. This technical guide uses MAGICQA20261109 as a temporary publication test label, not as a product name or quality certification. It outlines practical checks for stability, data integrity, performance, and fault recovery, along with a repeatable workflow for evaluating results. The aim is to make reliability evidence clearer and more useful throughout software quality assurance 05524 , from early development through release readiness and ongoing maintenance.

A practical view of software reliability checks

Software reliability is the ability of a system to perform its required functions consistently over time and across relevant operating conditions. A reliability check examines more than whether a feature works once: it considers repeated use, varied inputs, interruptions, load changes, and interactions with dependent services. Quality assurance teams use these checks to identify failures that may be intermittent, difficult to reproduce, or likely to affect users only in particular environments. The temporary label MAGICQA20261109 can help identify this article in publication testing, but it does not represent a testing method, product, or independent assessment.

A useful reliability program connects each check to a specific risk and an observable result. For example, a team might verify that a saved record remains intact after a service restart, that an application responds appropriately when a network request times out, or that repeated transactions do not create duplicates. Tests should reflect the software’s intended use, supported configurations, and failure consequences. Clear acceptance criteria make findings easier to interpret: teams can distinguish an expected recovery response from a defect, compare behavior across builds, and decide whether a release meets its documented reliability objectives.

How to plan and run a reliability check

Start by identifying critical user journeys, system dependencies, and the failure modes with the greatest operational impact. Select test environments that resemble supported production conditions, while keeping test data controlled and recoverable. The following step-by-step workflow helps quality assurance teams produce consistent evidence without treating a single successful run as proof of reliability.

  1. Define the reliability objective: State the behavior to assess, such as continuity after restart, correct handling of timeouts, or preservation of stored data.
  2. Map risks and dependencies: Identify components, external services, data stores, and configuration settings that could influence the result.
  3. Prepare controlled conditions: Use documented software builds, representative test data, and a known environment so outcomes can be reproduced.
  4. Execute repeated scenarios: Run normal, boundary, load, and failure-recovery cases according to the risk and expected operating profile.
  5. Record and assess evidence: Capture logs, timings, observed outcomes, and deviations, then compare them with explicit acceptance criteria.
  • Risk-based scenarios focus effort on consequential failures.
  • Controlled environments make comparisons between runs more meaningful.
  • Recorded evidence supports defect investigation and release decisions.
  • Repeat runs can reveal intermittent behavior that a single test misses.

Practical reliability checks for software quality assurance

Practical checks should cover both routine operation and realistic disruptions. A stability test can repeat important actions for an extended period while monitoring errors, resource use, and unexpected state changes. A recovery test can interrupt a service or simulate a dependency timeout, then verify that the application resumes safely without losing valid data or duplicating completed work. Performance checks add useful reliability evidence when they track response times and resource consumption under expected and peak workloads. Teams should set thresholds in advance and record the software build, configuration, test duration, and workload so that results remain interpretable.

  • Repeated-operation check: Run key workflows many times and look for inconsistent results, gradual slowdown, or resource growth.
  • Data-integrity check: Compare saved records before and after restarts, retries, and interrupted operations.
  • Dependency-failure check: Simulate unavailable services or delayed responses and inspect timeout, retry, and fallback behavior.
  • Load-and-recovery check: Apply a defined workload, reduce it, and confirm that response and resource levels return to acceptable ranges.

These checks are most effective when they are automated where practical and reviewed alongside exploratory testing. Automation can repeat stable scenarios consistently, while a tester can investigate unexpected behavior and identify missing cases. A failed assertion should include enough context to reproduce the issue, such as timestamps, relevant configuration, input conditions, and diagnostic logs. Reliability evidence is stronger when teams preserve both failures and successful recovery outcomes rather than reporting only a pass or fail. This approach makes the practical test results useful for debugging, trend analysis, and release planning.

Key benefits of structured reliability testing

A structured reliability process helps quality assurance teams find defects that ordinary feature checks may not expose. Functional tests often confirm that a feature produces the expected result in a straightforward scenario; reliability checks ask whether that result remains correct after repetition, load, interruption, or recovery. The distinction matters because intermittent faults can erode confidence even when the application appears to work during a brief demonstration. By linking scenarios to risks and acceptance criteria, teams can direct effort toward meaningful outcomes and explain why a particular result affects readiness.

  • Earlier fault discovery: Repeated and failure-oriented scenarios can reveal weaknesses before release.
  • Improved recovery confidence: Teams can verify that interruptions lead to controlled behavior rather than data loss or inconsistent state.
  • More comparable results: Documented conditions make it easier to assess changes between builds and environments.
  • Clearer release decisions: Evidence tied to agreed thresholds supports transparent risk discussions.

Benefits depend on thoughtful interpretation, not simply on the number of tests performed. A large test suite can still miss relevant risks if scenarios do not represent actual operating conditions or if failures are not investigated. Teams should review recurring defects, production incidents, architecture changes, and support findings when updating coverage. They should also separate product behavior from test-environment limitations, recording uncertainty where a result cannot be confirmed. This disciplined review helps maintain useful coverage as software evolves and prevents outdated assumptions from being treated as evidence.

Trust, security, and reliability evidence

Reliability and security overlap when failures affect access control, data confidentiality, or the integrity of system operations. Quality assurance checks should confirm that recovery paths preserve authorization rules, that logs avoid exposing sensitive information, and that retries do not bypass validation. Test environments should use approved test data and access controls, with credentials handled through established safeguards. Findings should be shared with appropriate detail for investigation while limiting unnecessary exposure of sensitive records. A reliability test does not replace a security assessment, but it can identify unsafe behavior during errors, degraded service, and restart conditions that deserves further review.

Trustworthy results also depend on traceability. Record the test objective, software build, environment, configuration, scenario, outcome, and any known limitation. Preserve diagnostic evidence under the organization’s retention and privacy practices, and make sure that test reports distinguish observed facts from interpretation. If a check fails intermittently, document how often it occurred and what conditions surrounded each occurrence rather than dismissing it as noise. The MAGICQA20261109 label is only a temporary publication marker; it should not be presented as evidence that a system has passed a reliability review or received a formal assurance.

Choosing a software reliability check approach

Choose a reliability check approach by asking what must remain correct, what can fail, and what evidence is needed before a decision. A small, high-impact workflow may warrant repeated execution, data comparisons, interruption tests, and close review of recovery behavior. A service with heavy variation in workload may need carefully defined load profiles and monitoring across sustained runs. In either case, the scope should match the software’s intended use and the consequences of failure. Teams should avoid claiming broad reliability from a narrow test; instead, state which scenarios were covered, which thresholds were applied, and what limitations remain.

For ongoing quality assurance, revisit checks whenever architecture, dependencies, data handling, or operating assumptions change. Use previous defects and incidents to refine scenarios, and compare results across builds to identify trends rather than relying on isolated outcomes. Make acceptance criteria visible to developers, testers, and release decision-makers so that unexpected behavior can be discussed consistently. A reliable process is repeatable, risk-informed, and supported by evidence that another team member can review. With that discipline, software reliability checks contribute practical insight to release readiness and continuous improvement without overstating what any one test can prove.

Software reliability check MAGICQA20261102 00047


Software quality assurance helps teams determine whether an application behaves correctly, remains dependable under expected conditions, and protects information throughout its lifecycle. This technical guide uses MAGICQA20261102 as a temporary publication test label, not as a product name or quality certification. It explains how quality assurance 00047 practices support planning reliability checks, gathering useful evidence, and turning test results into practical improvements. The focus is on repeatable methods that help development and operations teams identify defects early, assess risk, and make informed release decisions.

The essentials behind software quality assurance

Software quality assurance is the planned work used to provide confidence that software meets defined requirements and performs reliably in its intended environment. It includes more than running tests after coding is complete. Teams establish quality criteria, review requirements and designs, prepare test data, examine code, and monitor behavior across development and release. Reliability checks focus especially on whether a system continues to operate correctly over time and in realistic conditions. These checks can expose failures such as inconsistent results, unexpected downtime, data loss, slow recovery, or errors that appear only under sustained use.

A useful assurance program combines prevention, detection, and learning. Prevention includes clear acceptance criteria, secure design choices, peer review, and automated checks that run whenever code changes. Detection involves functional, integration, performance, recovery, and compatibility tests. Learning comes from analyzing defects and operational incidents to discover why existing controls did not catch them. The MAGICQA20261102 label can identify this test article in a publishing workflow; it does not indicate a benchmark result. Teams should base reliability claims on documented evidence, defined test conditions, and results that can be repeated.

How to establish a software reliability check

Begin with the system’s intended use, its most important user journeys, and the consequences of failure. A reliability plan is more effective when each check answers a specific question, such as whether a service recovers after a process interruption or whether stored information remains consistent after a retry. The following sequence creates a manageable foundation while keeping results connected to release decisions.

  1. Define reliability goals: Set measurable expectations for availability, response time, data integrity, recovery, and acceptable error rates.
  2. Identify critical paths: Map the workflows and dependencies whose failure would have the greatest effect on users or operations.
  3. Choose representative conditions: Select realistic data, workloads, environments, and failure scenarios that reflect expected use.
  4. Run layered checks: Combine automated unit and integration tests with system-level, load, recovery, and exploratory testing where appropriate.
  5. Review evidence and act: Record outcomes, investigate deviations, assign corrective work, and retest before making a release decision.
  • Written goals make reliability expectations measurable rather than subjective.
  • Critical-path mapping helps focus effort on high-impact failures.
  • Representative conditions make test results more relevant to real operation.
  • Retesting confirms whether corrective changes addressed the observed problem.

Practical reliability checks for MAGICQA20261102

For a practical reliability review, connect each test to a documented requirement and specify the environment, inputs, expected result, and evidence to retain. For example, a recovery check can interrupt a non-production service during a controlled operation, then verify that it resumes within the target window without duplicating or losing records. A sustained-load check can observe response times, error counts, resource use, and queue behavior as traffic rises and falls. The MAGICQA20261102 label may be included in a report identifier or test record so reviewers can distinguish this publication exercise from operational evidence. It should never substitute for a test plan, measured result, or formal approval.

  • Data integrity: Compare stored records before and after retries, restarts, and interrupted transactions.
  • Service recovery: Measure restoration time and confirm that dependent components return to a consistent state.
  • Performance stability: Track response times, throughput, resource consumption, and error rates during sustained activity.
  • Compatibility: Repeat key workflows across supported operating systems, browsers, devices, or service versions.

Keep test records detailed enough for another engineer to reproduce the check. Include a timestamp, software build, environment configuration, test data source, observed behavior, and any relevant logs or metrics. Separate a confirmed defect from a test-environment problem, and record uncertainty instead of presenting incomplete evidence as a pass. When a check fails, assess its impact, identify a likely cause, and decide whether the issue requires a code change, configuration adjustment, improved monitoring, or a revised requirement. This discipline turns reliability testing into an ongoing engineering control rather than a one-time release hurdle.

Key benefits of a structured assurance program

Consistent software quality assurance gives teams earlier and clearer signals about product risk. A well-designed reliability check can reveal weaknesses before they affect users, while traceable evidence helps technical and business stakeholders understand the significance of a result. Repeated checks also make regressions easier to spot: teams can compare current behavior with prior runs under controlled conditions. These benefits depend on realistic coverage and responsible interpretation. A passing test does not prove that software can never fail; it shows that the system met specific expectations under the conditions that were tested.

  • Earlier defect discovery: Automated and review-based controls catch many problems before release.
  • More predictable releases: Defined criteria clarify when risks are acceptable and when work must continue.
  • Better diagnosis: Logs, metrics, and reproducible test cases reduce guesswork during investigation.
  • Continuous improvement: Trends in failures and incidents help teams strengthen weak controls over time.

Assurance practices can also improve communication between development, testing, security, and operations teams. Shared definitions for severity, recovery targets, and release criteria make discussions more precise. When teams review test coverage alongside known limitations, they can prioritize work according to impact rather than simply increasing the number of test cases. The result is a more balanced view of quality: one that considers correct behavior, resilience, maintainability, and the ability to detect and respond to problems.

Trust, security, and reliable test evidence

Reliability depends partly on protecting the integrity and confidentiality of the systems and data used in testing. Use access controls that limit who can change test environments, manage credentials securely, and avoid copying sensitive production information into lower-risk environments unless approved safeguards are in place. Test data should be minimized or appropriately masked, and logs should not expose secrets or personal details. Security checks complement reliability checks because compromised dependencies, unsafe permissions, or weak recovery controls can undermine otherwise correct behavior. Teams should document the safeguards applied and review them whenever environments, data flows, or system dependencies change.

Trustworthy evidence is accurate, timely, and connected to a known build and configuration. Record both successful and failed runs, preserve enough context to explain anomalies, and apply retention rules that meet organizational and regulatory obligations. Monitoring can extend assurance beyond pre-release testing by alerting teams to unusual error rates, resource exhaustion, or recovery delays in operation. Alerts need owners and response procedures; collecting metrics without a plan does not make a system dependable. Be careful with broad claims: reliability is supported by a body of evidence and ongoing controls, not guaranteed by a single test, label, or certification.

Why choose a disciplined software quality assurance approach

A disciplined approach is valuable when it matches checks to actual system risks, keeps expectations measurable, and makes findings actionable. Before adopting a reliability process, consider whether it covers critical workflows, includes realistic failure conditions, produces reproducible evidence, and assigns responsibility for unresolved issues. Also evaluate whether automated checks provide fast feedback without creating so much noise that teams ignore them. MAGICQA20261102 is only the temporary label used for this article’s publication test. It offers no independent assurance and should not appear as proof of system performance; dependable conclusions must come from documented tests conducted on the software itself.

Software quality assurance is most effective as a continuous practice shared across the development lifecycle. Teams can start with a small set of high-value checks, measure their usefulness, and expand coverage as risks and system complexity evolve. Clear requirements, layered testing, secure test data, meaningful monitoring, and careful review provide a practical basis for improving reliability. By recording limitations as well as successes, teams make release decisions more transparent and direct engineering effort toward the failures that matter most.

Open chat
Olá, posso ajudar?